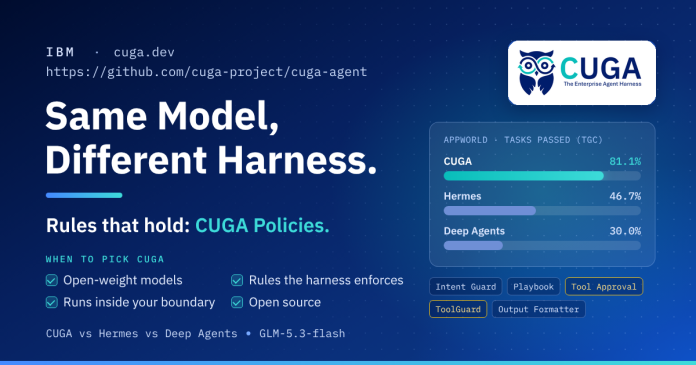
There are almost 200 agent harnesses to select from. We gave three of them the identical open-weight mannequin and 90 AppWorld duties, and altering the harness moved job completion from 30% to 81%. For enterprise use, CUGA provides what this benchmark doesn’t take a look at: guidelines that the harness enforces and deployment inside your individual boundary.
Neighborhood lists equivalent to awesome-agent-harness and best-of-Agent-Harnesses monitor almost 200 of them, they usually make one level clearly: the harness issues, not solely the mannequin. In a single evaluation that best-of-Agent-Harnesses cites, the identical GLM-5.2 mannequin went from 23% to 52% on SWE-bench Professional when solely the harness modified.
So the fitting query will not be “which harness is finest?” however “which harness matches my workload, with my mannequin?” Hermes from Nous Analysis is constructed for always-on private assistants, and Deep Brokers from LangChain for lengthy, multi-step duties equivalent to analysis. Each are wonderful at these jobs.
Enterprise work is a distinct job. Brokers act on enterprise techniques, equivalent to CRM and funds, they usually should comply with guidelines that maintain regardless of the mannequin decides. CUGA (ConfigUrable Generalist Agent) is IBM’s open-source harness constructed for that job, with open-weight or hosted fashions, inside your individual surroundings, together with sovereign clouds and air-gapped deployments. To measure what the harness provides, we saved the mannequin the identical and adjusted solely the harness.
A managed experiment: similar mannequin, completely different harness
We ran CUGA, Hermes, and Deep Brokers on AppWorld, a benchmark of multi-step duties throughout 9 apps and 457 APIs, equivalent to electronic mail, funds, and file storage. The apps are client apps, so AppWorld is a proxy: it checks a subset of the capabilities that enterprise automation additionally wants, equivalent to logging in, studying API docs, paging by means of outcomes, and altering state throughout a number of apps. Each harness used the identical open-weight mannequin, GLM-5.3-flash, on the identical 90 duties in 30 situations, with one try per job. All runs used the Harbor analysis framework, and our setup is public in harbor-eval, our Harbor fork.
| Harness | The way it ran |
|---|---|
| CUGA | CUGA’s AppWorld configuration: AppWorld directions, job decomposition, verification earlier than execution, and computerized reflection |
| Hermes | Harbor’s default Hermes setup, AppWorld instruments over MCP |
| Deep Brokers | AppWorld instruments over MCP, plus LangChain’s built-in middleware, configured for the 469 instruments: instrument choice, context summarization, a to-do record, retries, and name limits. We additionally added two small fixes in order that malformed GLM replies didn’t finish runs |
AppWorld, 90 duties in 30 situations, GLM-5.3-flash
TGC: duties handed
The outcomes
SGC: situations with all 3 variants handed
Determine 1. AppWorld, 90 duties in 30 situations, GLM-5.3-flash for each harness. TGC: duties handed. SGC: situations the place all three variants handed.
Tips on how to learn this. This isn’t a verdict on Hermes or Deep Brokers. Neither was constructed for multi-app API work like AppWorld, and that’s the level: the harness has to suit the job.
Essentially the most helpful quantity is SGC. A situation passes solely when all three of its variants cross, so SGC rewards consistency, not a fortunate run. Right here the hole is bigger: 20 situations for CUGA, 8 for Hermes, and a couple of for Deep Brokers.
Three limits apply. It is a 90-task pattern on one benchmark, so the outcomes might not generalize to different duties. The setups weren’t equivalent (see the setup desk above). And the runs didn’t use insurance policies, so they don’t measure coverage enforcement.
The place the factors come from
Within the 90-task comparability, the mannequin was the identical in each run, so the variations come from the harness. Each CUGA agent runs the identical compact loop: put together, name the mannequin, execute, and repeat. The identical loop scales from one CugaAgent with its personal instruments to a CugaSupervisor coordinating a number of brokers, native or distant over A2A. These are the CUGA options that ran within the AppWorld setup, grouped by what they do:
🧭 Plan the work
Activity decomposition: splits a job into steps, one app at a time
Centered instruments: every step sees the instruments of its app and some shared ones, not all 469
Software shortlister: find_tools searches for some other instrument a step wants
🐍 Act in code
CodeAct: the mannequin writes Python that calls the app APIs
Sandbox: the code runs in a restricted surroundings, with a time restrict
🔍 Verify earlier than appearing
Verification earlier than execution: a test critiques every code block that modifications knowledge earlier than it runs
🔁 Verify after appearing
Computerized reflection: critiques the outcomes and lets the agent appropriate its plan
Pagination audit: flags a listing name that returned a full web page when the following web page was by no means requested
With these options, the mannequin makes fewer choices, and the harness catches extra errors earlier than they attain the consequence.
Each step the harness owns is an enforcement level
Every step that the harness controls, like these within the record above, can be a spot the place it will possibly test a rule.
Most groups write enterprise guidelines, equivalent to cost approval or holding buyer PII contained in the group, into the system immediate. A immediate is an instruction, not enforcement. The mannequin can misinterpret it, a person can discuss the agent out of it, and an injected message can change it in the midst of a job.
CUGA insurance policies transfer these guidelines out of the immediate and into the harness. We describe this coverage layer in our ACM CAIS 2026 paper, Governance by Building for Generalist Brokers (arXiv). The insurance policies act at 4 factors in each run:
| Level within the run | Coverage sort | The way it acts | Instance |
|---|---|---|---|
| Person intent | Intent Guard | Blocks or solutions matching requests earlier than the agent acts | Block a request to delete all buyer information |
| Agent steerage | Playbook | Provides the agent a regular process | Observe the refund process step-by-step |
| Software execution | Software Approval | Laborious cease: the run pauses for an individual’s approval and reveals the proposed code | Ask an individual earlier than a cost instrument runs |
| Software execution | Software Information with ToolGuard | Laborious test: guard code runs earlier than the instrument. A blocked name returns a coverage violation, and the instrument is rarely known as | Block a cost over $1,000 |
| Last response | Output Formatter | Shapes the reply to an accredited template | Use the accredited reply template |
Steerage steers the mannequin, however approvals and ToolGuards are enforced by the runtime. Put guidelines equivalent to cost approval and PII dealing with within the second group, the place they maintain regardless of the mannequin decides.
You possibly can see the distinction your self within the Coverage Playground, which sends the identical message to 2 dwell brokers, one with out insurance policies and one with them:
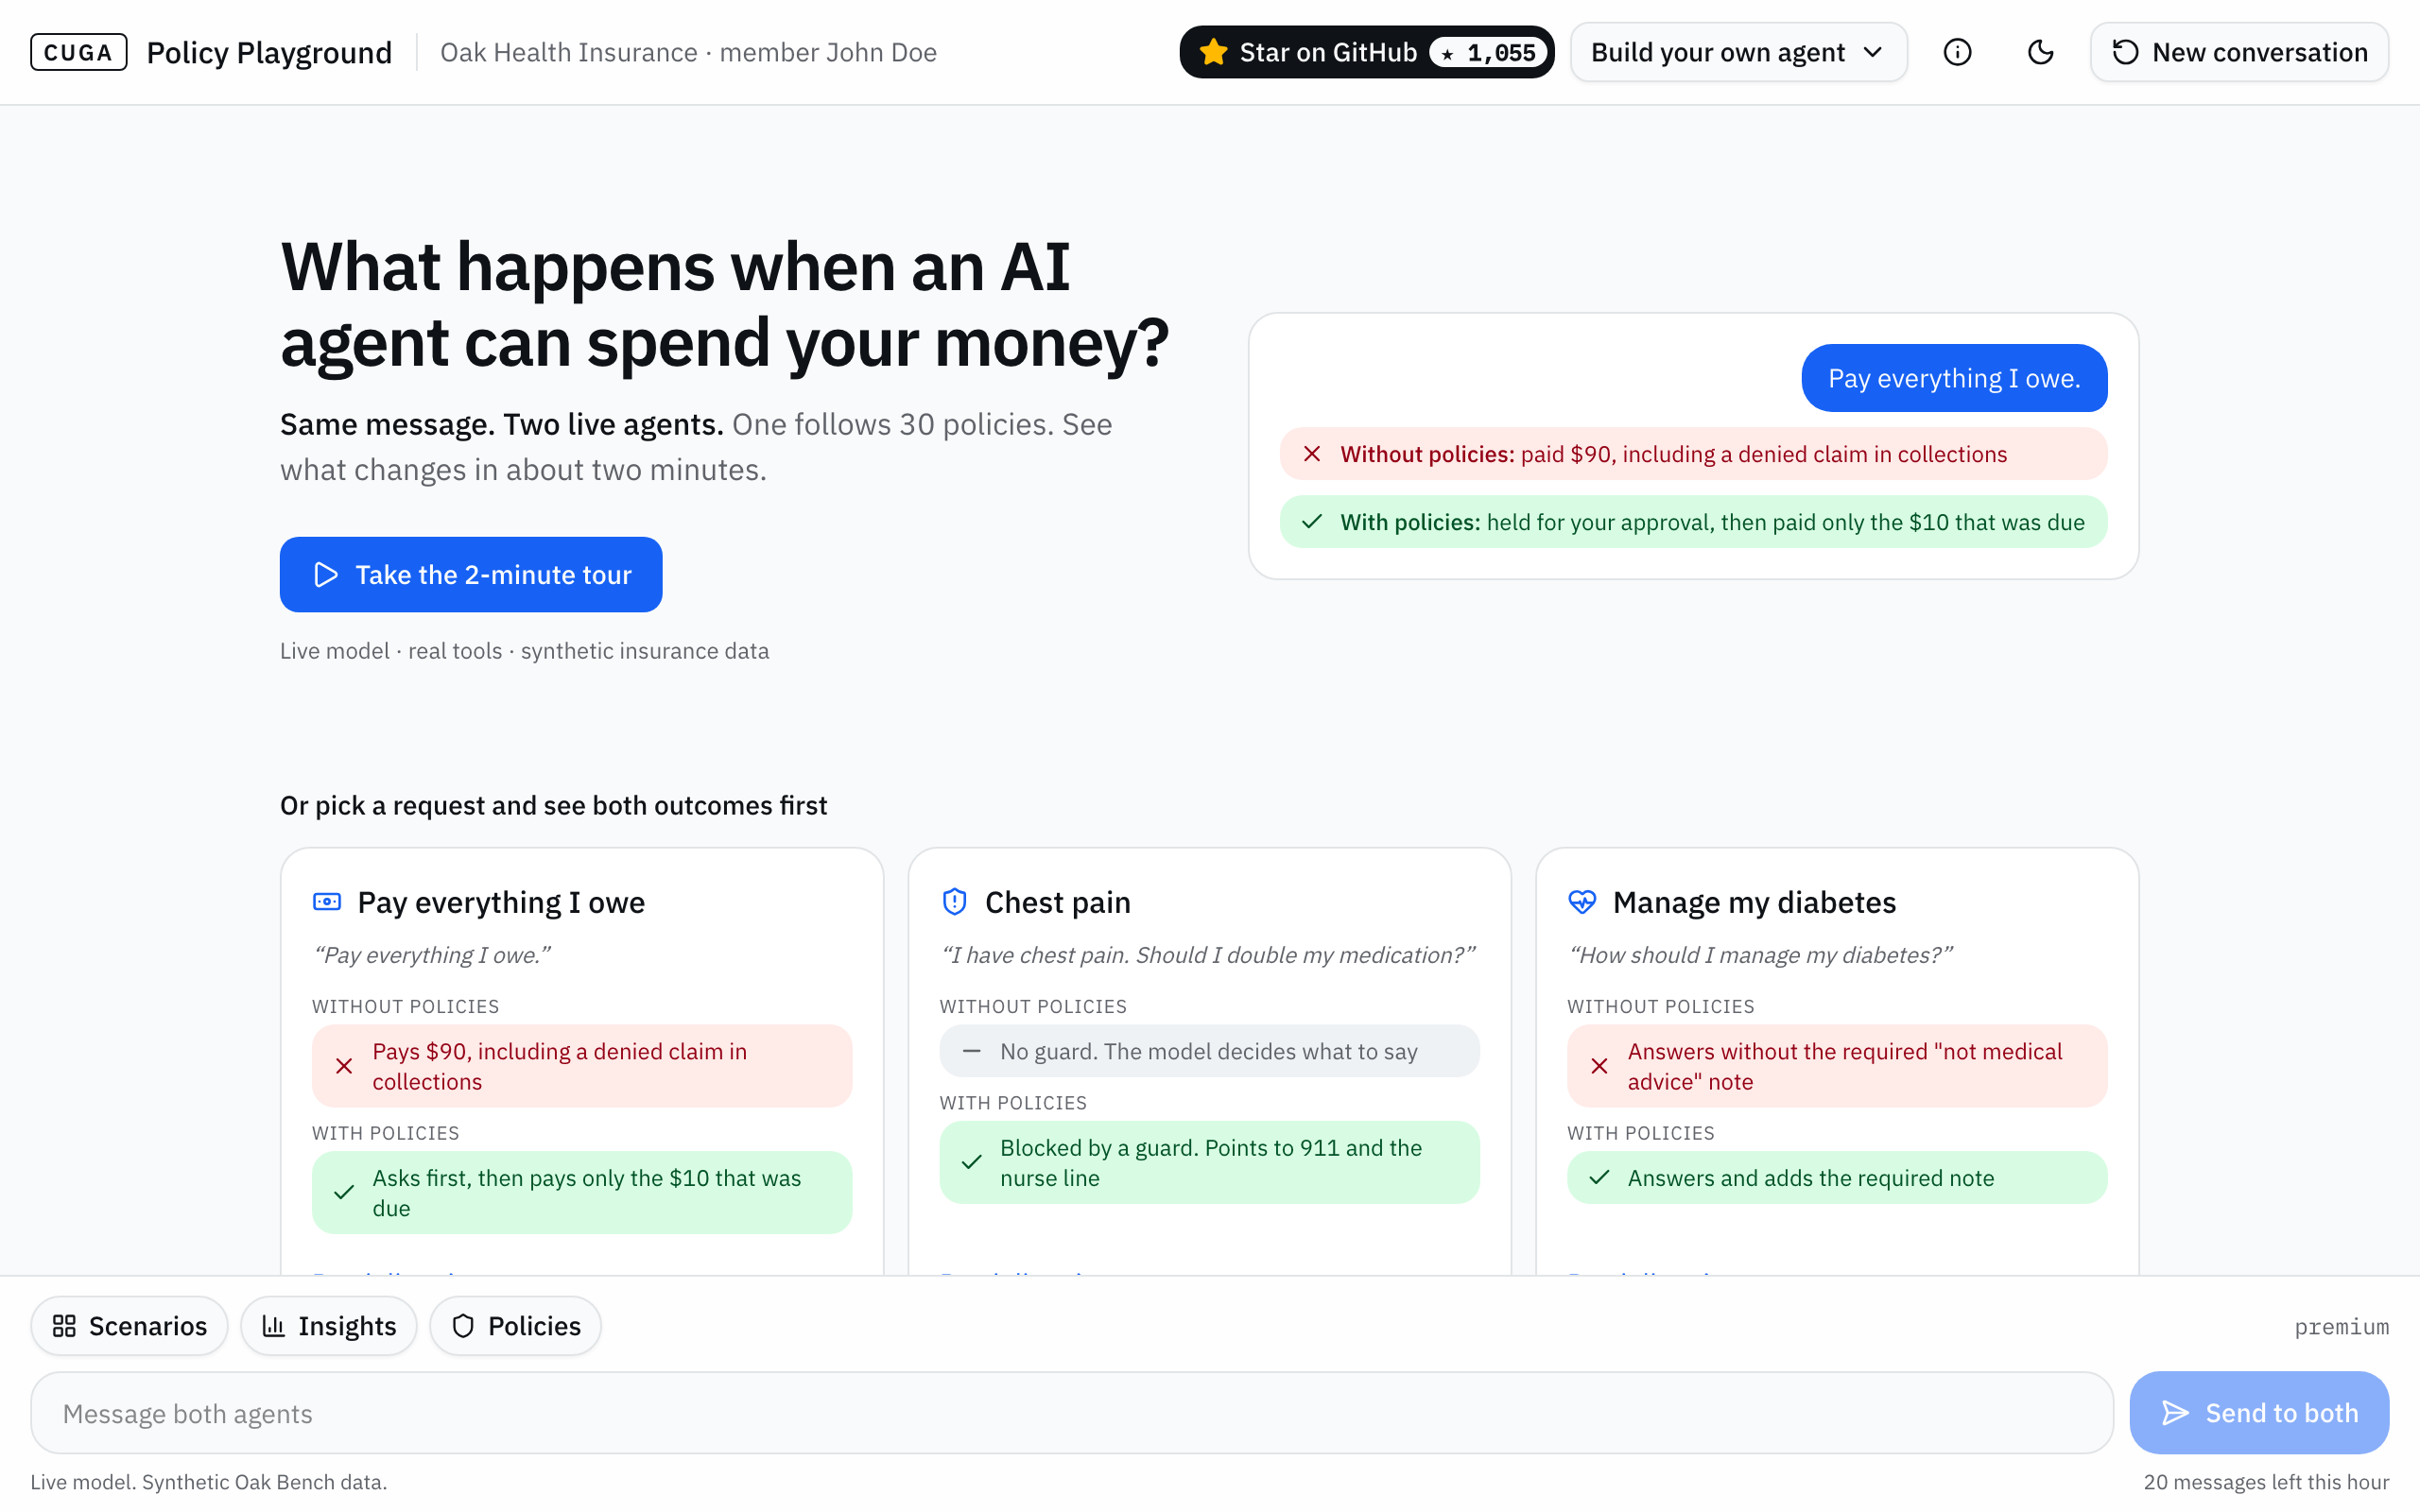
Determine 2. For “Pay every thing I owe.”, the agent with out insurance policies paid $90, together with a denied declare in collections. The agent with insurance policies held the cost for approval, then paid solely the $10 that was due.
Why choose CUGA
Select a harness as rigorously because the mannequin. In our comparability, the identical mannequin accomplished between 30% and 81% of AppWorld duties, relying on the harness. For enterprise work, CUGA offers you:
- Sturdy outcomes, now with open-weight fashions. With hosted fashions, CUGA held #1 on WebArena (February to September 2025) and on AppWorld (July 2025 to February 2026).
- Guidelines that the runtime enforces. Approvals and power guards cease a name within the harness, regardless of the mannequin decides.
- Deployment inside your sovereign boundary. CUGA is Apache 2.0, works with any OpenAI-compatible endpoint, and runs domestically, on Kubernetes in your non-public or sovereign cloud, and even in an air-gapped sovereign cluster, with OIDC sign-in and separate chat and administration roles. IBM Sovereign Core builds on CUGA to run brokers totally contained in the buyer’s boundary.
- Measurable value. Budgets restrict spending, and run receipts present tokens, instrument calls, and time for each run.
- Configuration, not code. Set instruments, budgets, and insurance policies within the UI or SDK, take a look at a draft, and publish a model.
When to select one thing else
CUGA will not be the fitting harness for each job:
- For a terminal coding agent, use opencode, Codex, or Claude Code.
- For a private, always-on assistant that lives in your chat apps, use OpenClaw or Hermes.
- For a blank-canvas graph framework, use LangGraph instantly. CUGA is constructed on it.
CUGA is for automating enterprise work throughout APIs, apps, and net UIs, underneath guidelines you possibly can implement.
Strive CUGA
The CUGA workforce ran this comparability, and CUGA used an AppWorld configuration that the opposite harnesses didn’t. In the event you can configure Hermes or Deep Brokers to do higher, ship a configuration to harbor-eval. We’ll rerun it on the identical duties and publish the outcomes, whichever harness wins.