TL;DR
NVIDIA Cosmos world mannequin growth platform provides 4 new open-weight checkpoints to its Cosmos 3 mannequin household for producing interactive world simulation and multi-sensor multi-view driving scenes:
All 4 fashions are post-trained examples of Cosmos 3 Nano and have 16B trainable parameters. The fashions use OpenMDW1.1, allowing industrial and non-commercial use below its phrases.
Obtain the checkpoints · Learn the technical report . Watch the demos
Why do you want these checkpoints?
🦾 Robotics wants environments that may reply this throughout altering scenes and viewpoints. These checkpoints provide complementary methods to construct them: Sim-Bimanual predicts visible penalties from actions, whereas Sim-Switch turns a physics simulator’s controls into generated observations.
🚦 For autonomous driving, look and geometry should agree. Synchronized digicam and LiDAR era connects visible observations with 3D sensing. Scene and traffic-signal controls let researchers fluctuate street layouts and sign states, then research how a driving coverage responds.
🔄 Every statement can form the subsequent motion. Streaming era connects video prediction to ongoing interplay, giving world-model researchers a strategy to discover how actions and observations unfold collectively.
🌐 An open basis for others to construct on. NVIDIA’s imaginative and prescient is to assist researchers and builders create richer, extra responsive simulated worlds. Open weights and post-training recipes present a shared place to begin for adapting fashions, evaluating strategies, and contributing enhancements. These issues stay laborious: the work forward is to measure the place the fashions faithfully help coverage studying and analysis, perceive their limits, and enhance the place they fall brief.
Construct Autonomous Car Worlds with Cosmos3-Nano
🌦️Transfer-Auto: driving eventualities → multi-sensor knowledge
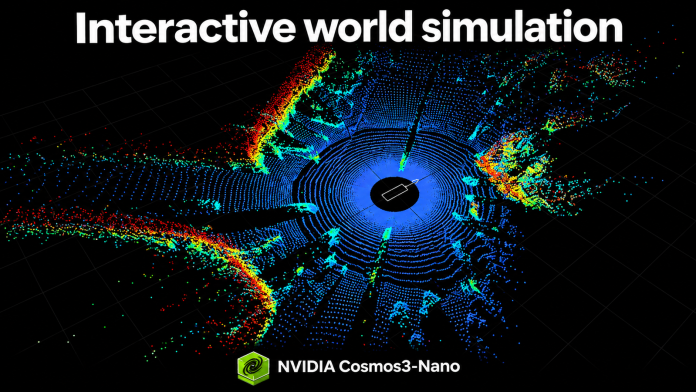
Cosmos3-Nano-Switch-Auto is a bidirectional mannequin for offline artificial driving knowledge era. It generates synchronized video throughout as much as 11 digicam views, together with fisheyes, and helps joint RGB–LiDAR era. Per-camera World State of affairs Map (WSM) controls specify scene construction and visitors movement, whereas textual content prompts information look.
Builders can fluctuate environmental circumstances to increase coaching and analysis protection, with non-obligatory preliminary RGB pictures to anchor scene look. Joint LiDAR era moreover makes use of aligned HD-map range-map controls.
Switch-Auto additionally serves as the inspiration for adapting Cosmos to your personal sensor rig and driving area. Begin by post-training it in your knowledge to accommodate your digicam structure, LiDAR configuration, and goal surroundings. The tailored mannequin can be utilized instantly for offline knowledge era or bear causal coaching and few-step distillation for quick streaming simulation—the event path used to create Cosmos3-Nano-Sim-Auto.
Level your agent to the open talent : Run inference with Cosmos3-Nano-Switch-Auto
Favor a pocket book? Open Switch-Auto.
🚗Sim-Auto: driving controls → streaming observations
Cosmos3-Nano-Sim-Auto is the causally distilled streaming variant of Switch-Auto. It generates successive small chunks of synchronized digicam video and LiDAR in just some denoising steps, utilizing generated historical past and up to date driving controls to help quick streaming and lengthy, interactive rollouts.
Present per-camera captions and synchronized WSM controls, optionally including preliminary RGB pictures. For LiDAR era, embrace HD-Map vary controls aligned with the digicam controls. The distilled mannequin generates successive chunks utilizing its rolling historical past. Closed-loop interplay requires a simulation runtime and WSM renderer to replace these controls from driving inputs. For a brand new sensor rig or area, adapt Switch-Auto first, then distill it into Sim-Auto.
Level your agent to the open talent : Run inference with Cosmos3-Nano-Sim-Auto
Favor a pocket book? Open Sim-Auto.
🎨 Sim-Switch: simulator controls → RGB
Your simulator computes movement, contacts, and bodily state. Sim-Switch makes use of its spatial controls and a textual content immediate to render shade observations {that a} coverage can eat.
Motion → simulator replace → spatial controls → generated RGB → subsequent coverage motion
-
Depth: relative distance from the digicam.
-
Segmentation: areas and object boundaries.
-
Edges: scene contours.
-
Blur: coarse look and structure.
Textual content guides look; physics and ground-truth state stick with the simulator.
Depth management to video
Segmentation management to video
Level your agent to the open talent : Run inference with Cosmos3-Nano-Sim-Switch
Favor a pocket book? Use Switch.
🤖 Sim-Bimanual: actions → video
Enter Frames
Output Video From Sim-Bimanual Simulation Checkpoint
Cosmos3-Nano-Sim-Bimanual simulates how an surroundings evolves in response to a bimanual robotic’s actions. It helps interactive two-arm simulation for YAM and AgiBot embodiments, managed by a coverage or human-operated joysticks.
Begin with a picture, transfer the robotic or digicam, and generate the subsequent observations. One management sequence can swap between viewpoint modifications and manipulation.
The mixed-action instance makes use of 59 management values, padded to 64 throughout coaching. Its schema defines coordinate frames, rotations, gripper calibration, validity masks, and management domains. Observe these conventions so every worth describes the supposed movement.
Maintain timing aligned: T transitions want T+1 observations. Coaching transforms uncooked captures into the mannequin’s motion illustration; launched inference actions are already normalized.
Right here, Sim-Switch generates visuals from a physics simulator’s up to date state; Sim-Bimanual generates the subsequent statement instantly from the scene and robotic actions.
See the information contract and motion schema.
Necessities: Linux, an NVIDIA GPU, Docker, and NVIDIA Container Toolkit. The revealed vLLM-Omni setup was examined on one GB200; this isn’t a minimum-memory specification. The server downloads weights; the purchasers fetch pattern inputs.
Level your agent to the open talent : Run inference with Cosmos3-Nano-Sim-Bimanual
Favor a pocket book? Open Bimanual
How streaming era works
Cosmos 3’s Combination-of-Transformers spine connects separate text-processing and visual-generation networks by means of consideration. The generator predicts every brief section from the immediate, out there controls, and generated historical past.
Controls + historical past → generate chunk → decode pictures → replace historical past
Denoising refines noisy, compressed video representations right into a section. Temporal-causal consideration lets it learn out there historical past and controls whereas blocking future goal observations. A key/worth cache retains consideration data for the subsequent prediction.
The mannequin operates on compressed video representations referred to as latents. After the preliminary picture, every latent time step represents 4 RGB frames. Switch predicts one step per chunk; the optimized Bimanual setup within the report predicts two. Smaller chunks let new controls have an effect on era extra typically.
The four-stage coaching recipe
-
Stage 0 — Bidirectional adaptation: study the area and its control-to-video relationships from full recorded clips.
-
Stage 1 — Instructor forcing: predict every chunk from earlier recorded observations and out there controls, with the clear reply and future targets masked out.
-
Stage 2 — Consistency distillation: use a frozen trainer to coach a scholar that generates every chunk in 4 denoising steps.
-
Stage 3 — Self-forcing: practice on the scholar’s generated historical past. A frozen trainer and an auxiliary rating mannequin provide the distribution-matching sign.
Why the ultimate stage issues: a barely mispredicted object turns into context for later frames, so errors can compound. Self-forcing exposes coaching to that generated historical past. Distillation and caching scale back the price of producing every statement.
🛠️ Adapt along with your knowledge
The post-training recipes begin from Cosmos3-Nano or suitable base weights and canopy all 4 phases. Maintain full coaching checkpoints to renew; exported inference weights omit optimizer and different coaching state.
-
Switch-auto: Put up-train in your driving knowledge to adapt to your sensor rig and area, and generate offline artificial knowledge.
-
Sim-auto: Apply causal coaching and distillation to an tailored Switch-Auto mannequin for quick streaming simulation.
-
Sim-Switch : Put up-train the checkpoint on your surroundings with native knowledge preparation, stage configurations, and resume.
-
Sim-Bimanual: Put up-train on your embodiment with knowledge validation, stage configurations, checkpoint handoffs, and export.
Give your coding agent the talent and dataset location. Observe the surroundings checks, validate a pattern, and check coaching and restart earlier than an extended run. Consider high quality on held-out episodes: a profitable brief run verifies execution, not convergence.
Extra Sources