Our newest launch, Apertus 1.5, extends the 8B and 70B Apertus 1.0 fashions with picture/audio understanding, an optionally available pondering mode, a 4 instances longer context window, improved instruction-following, and higher device use. The up to date 8B and 70B mannequin weights had been launched to Hugging Face on July 24, 2026 beneath an Apache 2.0 license. Additional particulars are actually accessible from the venture Technical Report, and summarized right here.
Apertus 1.5 is a continued pretraining of the primary technology mannequin: including 4 trillion tokens of textual content and multimodal coaching knowledge to the 8B mannequin and a couple of trillion tokens to the 70B mannequin, for a complete of 19T and 17T, respectively. As with each Apertus launch, the fashions are totally open: open weights, open knowledge, open values, and full coaching particulars.
Key Enhancements
- Native Multimodal Understanding: Apertus 1.5 accepts photographs and audio alongside textual content, bringing paperwork, diagrams, and pictures into the dialog. The fashions may also course of spoken language, although this stays experimental.
- Considering Mode: The fashions might be switched right into a pondering mode to motive in regards to the enter earlier than answering, which improves efficiency on reasoning issues.
- Lengthy Context: The context window grows to 262,144 tokens, a 4x improve over Apertus 1.0.
- Improved Instruction-Following: Higher instruction adherence than Apertus 1.0 offers extra predictable and correct responses.
- Improved Instrument Use: The fashions are educated for higher device integration, permitting simpler use of exterior instruments and APIs.
- Open Values: Stronger adherence to the Apertus Constitution, which brings transparency to the mannequin’s values and rules.
Coaching Course of

The total Apertus 1.5 coaching pipeline
Multimodality By means of the Tokenizer
We introduce multimodality in v1.5 fashions in an early-fusion method, the place photographs and audio enter Apertus as discrete tokens in the identical sequence with textual content tokens, as an alternative of utilizing a separate imaginative and prescient encoder. Pictures are tokenized with the Emu3.5 tokenizer (a 512×512 picture turns into 1,024 tokens) and audio with WavTokenizer (40 tokens per second). We solely prolong the vocabulary, so the structure stays unchanged and coaching runs at text-only pace. The fashions perceive photographs and audio however generate solely textual content.

Pre-Coaching
Ranging from Apertus 1.0, we proceed pretraining in 4 phases:
- Unpaired: textual content plus standalone photographs and audio, so the mannequin learns the brand new modalities.
- Paired: picture–caption and audio–transcript pairs, so it aligns them with language.
- Cooldown: higher-quality knowledge with extra math and code.
- Lengthy context: the window grows step-by-step from 8k to 262k tokens.
General, greater than half of the coaching tokens are text-only, which preserves the language skills of Apertus 1.0. The textual content knowledge is refreshed with sources equivalent to FineWeb2-HQ+, FinePDFs, and Nemotron-CC. All new knowledge, multimodal included, meets the identical bar as earlier than: publicly accessible, permissively licensed, and with robots.txt opt-outs revered retroactively. Each supply is listed in apertus-data-transparency.
Put up-Coaching
Put up-training runs in 5 phases: SFT → long-context SFT → RL → DPO → constitution alignment (SDPO).
- SFT on 3.7M textual content samples plus picture and speech knowledge. Reasoning traces are added solely to prompts the mannequin cannot already resolve with out them. Instrument-use knowledge is restricted to execution-verified trajectories. We launch the textual content SFT combine we used on Hugging Face.
- Lengthy-context SFT on the full 262k window restores the long-context skill that short-context SFT erodes.
- RL with verifiable rewards (RLVR) on about 350k math, code, instruction-following, multilingual, and imaginative and prescient prompts, mixing pondering on and off.
- DPO with judge-scored desire pairs improves chat high quality, device use, and security. We launch the desire pool and coaching pairs.
- SDPO aligns the mannequin with the Apertus Constitution by way of decide suggestions and self-distillation.
Analysis Outcomes
Alongside the prolonged mannequin capabilities, we additionally considerably expanded the scope of evaluations. Past the present text-based evaluations used for Apertus 1.0, we added multimodal evaluations (picture & audio), and thinking-mode evaluations.
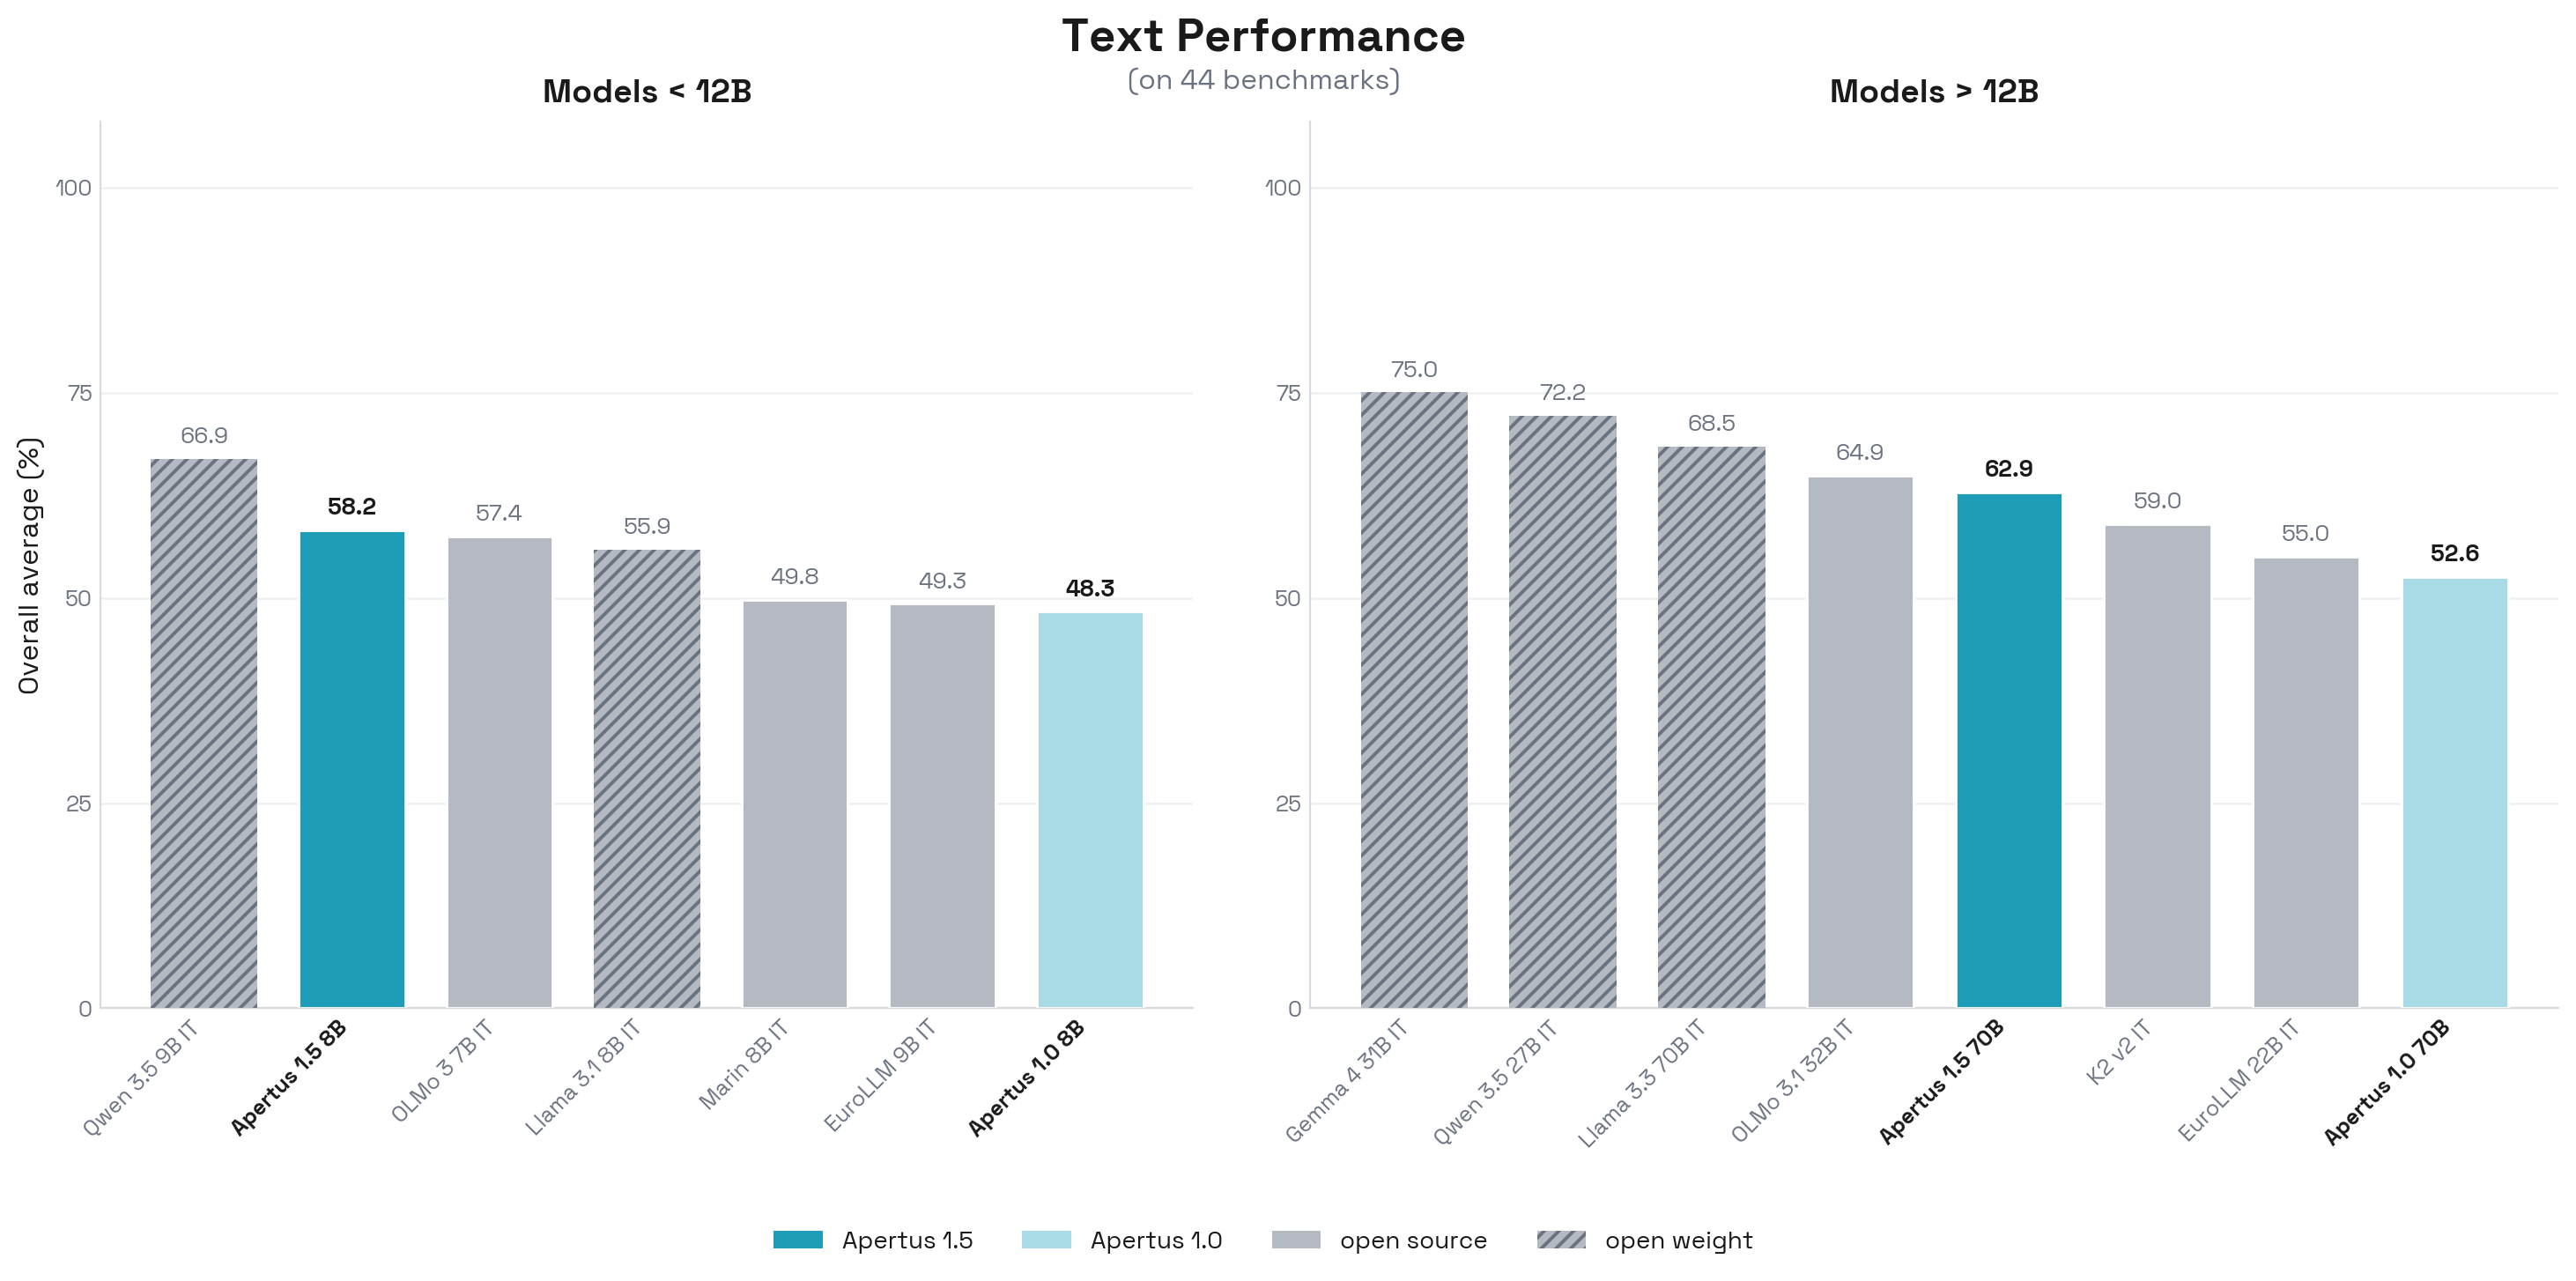
The multimodal evaluations are completed by way of MLLM-eval-suite pipeline, merging two main multimodal analysis frameworks lmms-eval and VLMEvalKit. We additionally added a sequence of text-based benchmarks, in addition to prolonged benchmarking for translation and multilingual capabilities, security, and gear use. These might be present in our post-training analysis repository, primarily based on lm-evaluation-harness fork.
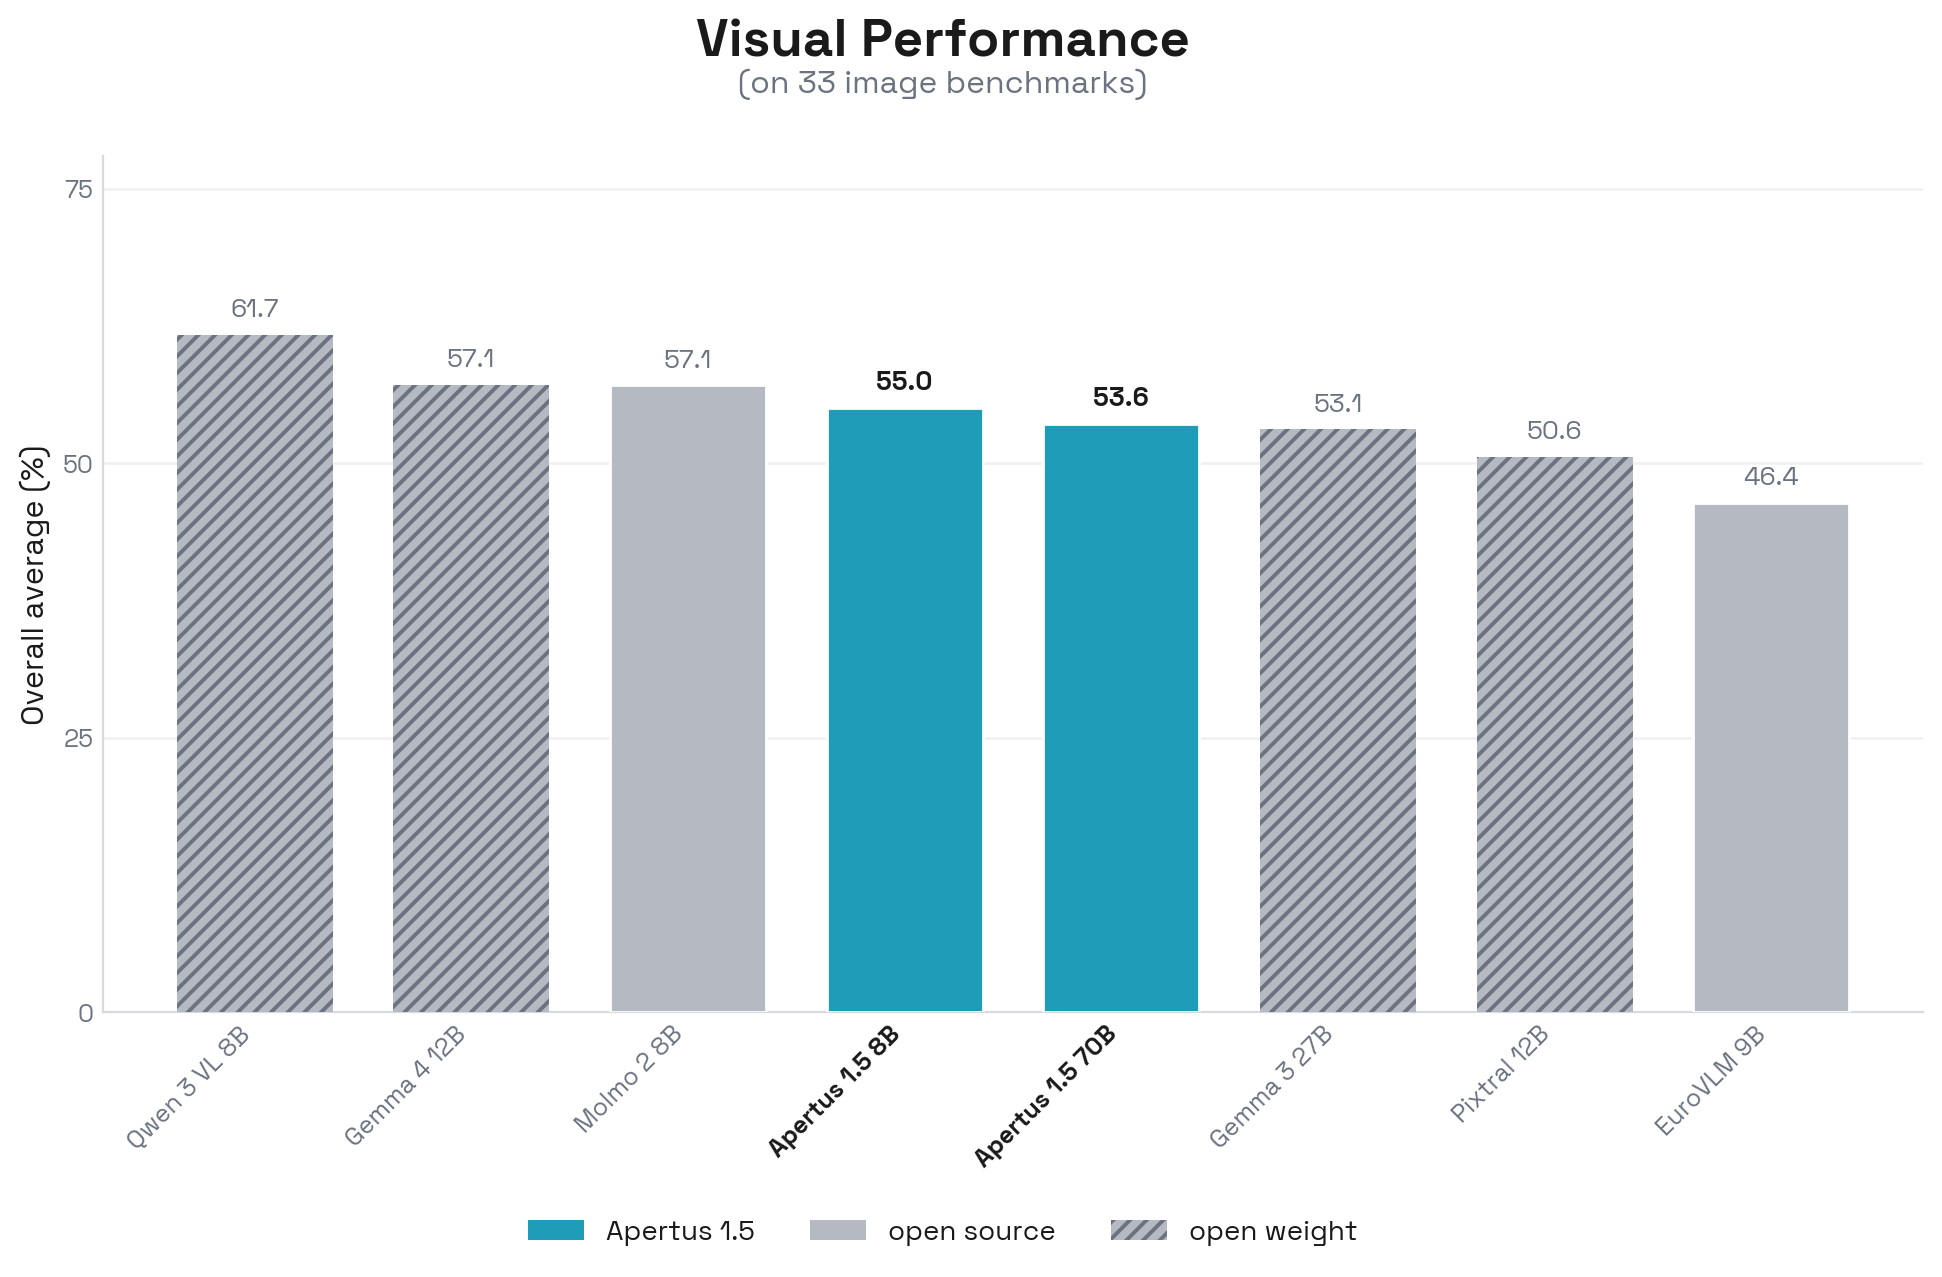
Whereas nonetheless trailing frontier open-weight fashions, the brand new launch has additionally considerably improved efficiency in coding and instruction following capabilities with Apertus 1.5 8B outperforming equally sized open-weight fashions on IF and multilingual duties. Considering additional improves efficiency on difficult reasoning-heavy benchmarks like AIME. The multimodal efficiency of the mannequin is nearer to Gemma 4 12B and different present open-weight fashions. Apertus 1.5 multimodal efficiency is aggressive in spatial understanding amongst open-weight fashions and doc/chart understanding amongst open-source fashions.
We additionally thank our collaborators and exterior evaluators for his or her assist with environment friendly benchmarking of Apertus capabilities. Specifically, Apertus 1.5 reveals robust efficiency on Swiss Authorized duties, being on par with main open-weight fashions (weblog, code). Moreover, on Final Translation Benchmark, Apertus 1.5 8B presents machine translation capabilities which match GPT-OSS-20B and outperform fashions like Claude Haiku 4.5 or Google Translate (leaderboard, paper).
Analysis Playing cards: Apertus ❤️ EvalEval
Apertus collaborates with the EvalEval Coalition to make sure totally clear and reproducible benchmarking. We publish the Apertus 1.5 ends in the Each Eval Ever (EEE) schema, a shared format that information not solely scores, but additionally who ran the analysis, how the mannequin was accessed, the technology settings, and the way every metric must be interpreted: particulars which are routinely lacking from leaderboards and that always clarify why similar-looking scores differ.
The outcomes are proven within the Eval Card beneath, which mixes the run knowledge with benchmark and mannequin metadata into one interpretable report, and are additionally accessible by way of Hugging Face Group Evals. This is identical infrastructure the UK AI Safety Institute makes use of to publish its evaluations brazenly. Since our textual content evaluations run on our public fork of lm-evaluation-harness, which EEE helps with a devoted converter, anybody can rerun them and evaluate their numbers in opposition to ours beneath an identical settings.
Structured analysis reporting additionally issues past analysis. EvalEval has mapped Analysis Playing cards to AI governance necessities, together with Article 55 of the EU AI Act and the GPAI Code of Follow, and located that the EEE schema can signify 56 of the 60 evaluation-reporting components these frameworks name for. This matches how we already launch Apertus: alongside the fashions, we publish a Public Abstract of Coaching Content material and, voluntarily, a Code of Follow doc. Machine-readable analysis information are a pure subsequent step: making it simpler for regulators, deployers, and researchers to seek out, interpret, and evaluate the proof behind a mannequin.
We’re dedicated to selling reproducible and clear analysis by way of Eval Playing cards and the EEE schema, and encourage different mannequin builders to report their ends in the identical method, in order that scores might be in contrast throughout fashions and organizations.
Apertus 1.5 Reproducibility
All recipes, ablations, and knowledge mixtures are documented within the Technical Report. We purpose to popularize open mannequin improvement by making the v1.5 coaching course of public and accessible. Intermediate checkpoints are hosted in our Apertus 1.5 Hugging Face assortment, together with the bottom weights, SFT, RLVR and DPO, in addition to our curated coaching knowledge mixes/customized datasets in Apertus 1.5 datasets assortment. Sharing them permits researchers to analyze how every stage modifications the mannequin conduct.
The report covers quite a few ablations on the impact of post-training knowledge in several phases, the place we noticed that the multimodal knowledge combined in along with textual content knowledge throughout SFT helps enhance throughout all modalities. We additionally discover that the advantages of multimodal reasoning traces survive the following text-only reinforcement studying: ranging from an SFT checkpoint educated with multimodal traces, RL improves arithmetic greater than when ranging from a text-only checkpoint, and the benefit on reasoning duties persists all through coaching.
| Stage | Information | Code / recipe |
|---|---|---|
| Pre-training: Levels 1–2 (unpaired, paired) | All sources with variations and licenses in apertus-data-transparency; imaginative and prescient and audio processing recipes in multimodal-data | Megatron-LM, launch scripts in pretrain-code, apertus-omni-tokenizer, benchmark-image-tokenizer, benchmark-audio-tokenizer (incl. interleaved speech–textual content builder) |
| Pre-training: Stage 3 (cooldown) | apertus-data-transparency; curated picture datasets NASA, Our World in Information, Smithsonian, swisstopo | Megatron-LM, launch scripts in pretrain-code |
| Lengthy-context extension | apertus-data-transparency; artificial long-context duties in LongContextQA | Megatron-LM, launch scripts in pretrain-code |
| SFT | Apertus-v1.5-SFT-mix (multimodal SFT combine listed within the report) | posttraining-data, Megatron-LM (SFT launch scripts) |
| Lengthy-context SFT | Subsets of the SFT combine (listed within the report), plus LongContextQA duties | Megatron-LM |
| RL (RLVR) | Combination listed within the report | verl, verl-recipe |
| DPO | Apertus-v1.5-Desire-Pool (annotated completions), Apertus-v1.5-Desire-Information (pairs) | posttraining, verl |
| SDPO (constitution alignment, 8B solely) | gretelai/gretel-safety-alignment-en-v1 | self-distillation |
Mannequin Availability
Proton Lumo and Infomaniak Euria are two extensively used apps which have lately built-in Apertus 1.5. These deployments are linked within the Group Showcase amongst others – see this dialogue thread for a preview.
Entry to Apertus 1.5 within the type of an API for builders has been introduced by a spread of suppliers, together with Swisscom, Infomaniak, Phoeniqs, and different corporations listed in our Common Availability information. The report additionally supplies particulars on how we work with exterior evaluators to check and put together the fashions.
Technical directions for working the fashions are within the mannequin playing cards of the Apertus releases on Hugging Face and in our Quickstart information.
Tips on how to Get Concerned
Thanks for studying this weblog submit and being a part of our group! We simply celebrated 5 million downloads in our Hugging Face analytics 🤗 and are usually not slowing down. On the current AI+X Summit in Zurich, our workforce introduced the roadmap for Apertus 2.0: sparse/MoE structure, ~600B complete parameters, prolonged coaching schedule, with brokers, arithmetic and coding as priorities.
In abstract: we invite you to learn our report, obtain the fashions, discover the intermediate checkpoints, finetune the weights, and reproduce our evaluations. Questions that aren’t already coated in our publications or web site FAQ are at all times welcome, and we’d additionally love to listen to which subjects could be most helpful to the group for future deep dives.
For those who construct with or use Apertus, please fill out the Showcase kind, and attain out by way of the choices on our Contact web page. We’re wanting ahead to highlighting extra work, studying what you’re constructing, and listening to how Apertus might be improved!
Quotation
Mission Apertus, et al. “Apertus 1.5: From Open Textual content Fashions to Open Multimodal Reasoners.” arXiv:2610.15542. Preprint, arXiv, October 11, 2026. https://doi.org/10.48550/arXiv.2610.15542.
@misc{apertus2026apertus15opentext,
      title={Apertus 1.5: From Open Textual content Fashions to Open Multimodal Reasoners},
      creator={Mission Apertus and Yixuan Xu and Yassine Turki and Vinko Sabolčec and Valentina Pyatkin and Tommy Chu and Sven Najem-Meyer and Sean F. Carroll and Robert Smith and Raphael Kreft and Oscar Alessandro Tazza and Oleg Lavrovsky and Nicola Irmiger and Matteo Santelmo and Marian Schneider and Juan García Giraldo and Hanna Yukhymenko and Eduard Ďurech and Davit Melikidze and Dani Tamayo and Bettina Messmer and Aryan Ahadinia and Anunay Yadav and Allen Huang and Ahmad Fraij and Alessandro Bombarda and Alex Padula and Alexander Hägele and Alexander Sternfeld and Anna Hedström and Anna Kosovskaia and Arthur Wuhrmann and Arundhati Balasubramaniam and Badr Al Mahouri and Barna Pasztor and Bartosz Szostakiewicz and Bich Ngoc Doan and Bryan Schmid and Burak Sezen and Camille Challier and Clément Charmillot and Dana Shayakhmetova and Daniel Perruchoud and David Brüggemann and David Isztl and Elia Palme and Emma Anastassova and Fabian Bösch and Faruk Zahiragić and Fawzi Roberto Mohamed and Fiona Panicali and Florian Kolly and Flynn Guerra and Francesco Monti and Frederike Lübeck and Gennaro Oliva and Haofeng Yang and Haoliang Shang and Helen El Khoury and Henrique Mendonça and Jannis Vamvas and Jérome Landolt and Jessica Lam and Jingchun Xiao and Jonathan Coles and Joshua Oyebanji and Khanh Nguyen and Konstantinos Pitas and Lasse B. Strand and Li Mi and Loïc Deslarzes and Lorenzo Baggi and Lorenzo Noci and Luca Baumann and Luca Sartori and Lukas Drescher and Marco De Negri and Marco Passerini and Mark Klein and Marko Stojanovic and Martin Majsec and Matin Ansaripour and Mattea Busato and Mauro Pellonara and Max Neuwinger and Michael Graber and Michal Tešnar and Michelle Wastl and Miguel Gila and Mikolaj Boronski and Morgane Magnin and Moritz Reihs and Mukhammadali Sayfiddinov and Nathan Ranchin and Nicolas Cuveillier and Oscar Wohlfahrt and Qianqian Zou and Rada Kamysheva and Rita Sevastjanova and Roman Machacek and Sebastian Keller and Simon Matrenok and Simon Pierre and Stefano Schuppli and Suei-Wen Chen and Szabina Horváth-Mikulas and Taliesin Perez and Thilo Spinner and Thomas Kleine Buening and Tim Robinson and Tymoteusz Kwiecinski and Vilém Zouhar and Vinzenz Thoma and Xiaozhe Yao and Yannick Metz and Yuhei Fukuhara and Yusif Askari and Zixuan Chen and Alexander Ilic and Ana Klimovic and Andreas Krause and Andrei Kucharavy and Elliott Ash and Joost VandeVondele and Martin Rajman and Mennatallah El-Assady and Thomas Schulthess and Timo Kehrer and Torsten Hoefler and Antoine Bosselut and Martin Jaggi and Imanol Schlag},
      12 months={2026},
      eprint={2610.15542},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2610.15542},
}